Knowledge evals
End-to-end checks of memory: remember() then query() against the real LLM, verifying the temporal facts that were stored and the answer that came back.
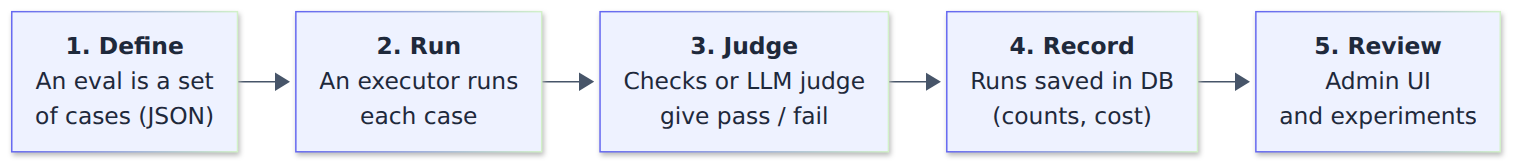
- Evals: an eval is a set of cases, each one JSON: the texts to remember (with their
reference_time), a question, and what must hold. Built-in cases cover a simple fact, a job change, a 60-person document split into ~20 chunks, web search and timeseries ingestion. - Programmatic checks, no judge:
expect_edgesasserts a fact exists between two entities with the rightvalid_at/invalid_atand whether it was closed;expect_containsasserts the answer mentions what it should. Further checks cover chunks, web searches and stored series. - Contradictions tested: "Alice works at Acme", then "Alice started at Globex": the Acme fact must be closed at that date, the Globex one live, and "Where does she work now?" must answer Globex.
- Eval mode: with
serve --evalthe server adds/v1/gb/eval/rememberand/v1/gb/eval/query, which return an ATIF trajectory of the call: every prompt, raw model output, tool step, token count and cost. - Compare models and reasoning per stage: choose the model and thinking level of
extract_graph,resolve_edgesand others, change one stage per run, and see which facts each model got wrong and what it cost. - Experiments: every run is saved in a separate eval database, with its own datasets, results and trajectories, never reset, so runs can be compared later in the admin UI.